Arama sonuçları
Building Llama Cpp For Nvidia Gpu Llm İnference İn 2026
 32:04
Building llama.cpp for NVIDIA GPU LLM Inference in 2026
YourAvgDev
1 B görüntüleme · 1 ay önce
 33:31
Building llama cpp for CPU LLM inference in 2026.
YourAvgDev
1,1 B görüntüleme · 1 ay önce
 9:14
What Is Llama.cpp? The LLM Inference Engine for Local AI
IBM Technology
198 B görüntüleme · 8 ay önce
 8:19
NVIDIA Just Made llama.cpp 41% Faster at Long Context (Free Update)
SimplyExplain
13 B görüntüleme · 4 gün önce
 8:55
llama.cpp Just Made Your GPU 2x Faster on Big Models (Turn This On)
SimplyExplain
40 B görüntüleme · 2 hf. önce
 14:56
Build from Source Llama.cpp with CUDA GPU Support and Run LLM Models Using Llama.cpp
Aleksandar Haber PhD
6,4 B görüntüleme · 1 yıl önce
 10:36
Llama.cpp vs vLLM: Which Local LLM Engine Actually Scales?
IBM Technology
131 B görüntüleme · 3 ay önce
 22:41
Run AI Models Locally with llama.cpp
That DevOps Guy
41 B görüntüleme · 6 ay önce
 11:36
Running a 22GB AI Model on a 6GB GPU, FAST (llama.cpp Guide)
Cloud Codes
24 B görüntüleme · 3 ay önce
 6:27
Build llama.cpp for Your GPU: 2 Commands, Then 1 Flag
Nyndra AI
71 görüntüleme · 2 hf. önce
 13:41
28 llama.cpp Flags You Should Know
Dainamo
5,8 B görüntüleme · 2 ay önce
 14:45
This New llama.cpp Fork Turns Your SSD Into VRAM (22 Tok/s)
Cian Mag
71 B görüntüleme · 9 gün önce
 8:53
Your llama.cpp Flags Are Outdated: The 2026 Settings That Actually Matter
Readheights AI
4,2 B görüntüleme · 1 ay önce
 36:31
IWOCL 2026 - Advancing OpenCL-Based LLM Inference in Llama.cpp on Qualcomm Adreno GPUs
The Khronos Group
158 görüntüleme · 5 ay önce
 11:02
Your local LLM is 10x slower than it should be
Alex Ziskind
258 B görüntüleme · 9 ay önce
 15:47
Running a 22GB AI Model on a Compact 6GB GPU, FAST (llama.cpp Guide)
Saad Explains
454 görüntüleme · 3 ay önce
 16:56
Build Powerful Local Coding Agent on Budget GPU with Llama.cpp and Pi
Codacus
122 B görüntüleme · 5 ay önce
 44:33
Building LLM Inference Engines in Java with TornadoVM and the NVIDIA Ecosystem by Thanos Stratikopo
Devoxx
440 görüntüleme · 1 ay önce
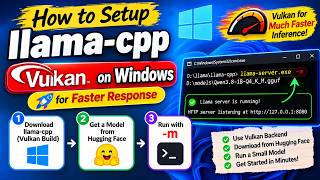 7:14
Run AI Locally on Any Windows PC (No NVIDIA Needed) with Intel Arc - llama.cpp + Vulkan
AN.AITechWorld
2,2 B görüntüleme · 1 ay önce
 13:18
Build llama.cpp from Source and Chat Offline on a 10 GB NVIDIA GPU
Works On My GPU
37 görüntüleme · 3 gün önce
Yüklenemedi. Lütfen tekrar deneyin.