Arama sonuçları
Direct Preference Optimization Dpo Explained Aligning Llms Without Rei
 23:30
Direct Preference Optimization (DPO) Explained: Aligning LLMs Without Reinforcement Learning
SH AI Academy
234 görüntüleme · 4 ay önce
 8:55
Direct Preference Optimization: Your Language Model is Secretly a Reward Model | DPO paper explained
AI Coffee Break with Letitia
44 B görüntüleme · 2 yıl önce
 21:15
Direct Preference Optimization (DPO) - How to fine-tune LLMs directly without reinforcement learning
Luis Serrano Academy
40 B görüntüleme · 2 yıl önce
 48:46
Direct Preference Optimization (DPO) explained: Bradley-Terry model, log probabilities, math
Umar Jamil
40 B görüntüleme · 2 yıl önce
 58:07
Aligning LLMs with Direct Preference Optimization
DeepLearningAI
34 B görüntüleme · 2 yıl önce yayınlandı
 6:18
4 Ways to Align LLMs: RLHF, DPO, KTO, and ORPO
Snorkel AI
6,2 B görüntüleme · 2 yıl önce
 16:57
Direct Preference Optimization (DPO) | Paper Explained
Outlier
3,9 B görüntüleme · 11 ay önce
 10:44
Direct Preference Optimization (DPO) - Learn how to fine-tune LLMs directly without RL.
Math Obsession
11 görüntüleme · 5 ay önce
 16:15
Direct Preference Optimization Beats RLHF (Explained Visually), how DPO works?
GeniPad
438 görüntüleme · 9 ay önce
 4:54
DPO: Alignment Without Reinforcement Learning
AI WITH Rithesh
106 görüntüleme · 3 ay önce
 59:41
How LLM Alignment Really Works: Reward Models, KL, PPO & DPO (1 Hour)
PARTH VADERA
65 görüntüleme · 2 hf. önce
 14:58
How LLMs Learn What Humans Prefer — DPO Explained
Jazon Jiao
521 görüntüleme · 2 ay önce
 8:34
Direct Preference Optimization (DPO) | Training LLMs to Align with Human Preferences | Uplatz
Uplatz
67 görüntüleme · 4 ay önce
 2:45
Direct Preference Optimization (DPO) Explained: AI Alignment
VLR Software Training
29 görüntüleme · 11 ay önce
 5:17
DPO - Your Language Model is Secretly a Reward Model
DataMListic
818 görüntüleme · 3 ay önce
 16:26
DPO Explained | RLHF Without Reinforcement Learning (Direct Preference Optimization)
Paper Explained
25 görüntüleme · 6 gün önce
 11:37
DPO Explained: Fine-Tuning LLMs Without a Reward Model
Agent Engineering
29 görüntüleme · 1 ay önce
 4:05
DPO Explained: Align a Language Model Without a Reward Model
Multi-Agent Academy
420 görüntüleme · 1 ay önce
 10:38
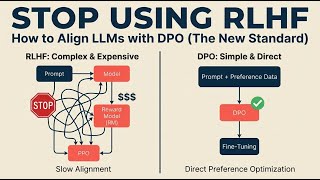
Stop Using RLHF: How to Align & Control LLMs (DPO Guide)
Shane | LLM Implementation
514 görüntüleme · 11 ay önce
 22:18
Direct Preference Optimization (DPO): End-to-End Implementation
SH AI Academy
132 görüntüleme · 4 ay önce
Yüklenemedi. Lütfen tekrar deneyin.