Arama sonuçları
Gpu Resizing For Llm İnference Explained Replace The Fleet
 0:45
GPU Resizing for LLM Inference Explained: Replace the Fleet
mnsAI
3 görüntüleme · 13 gün önce
 7:39
How One GPU Serves Thousands: LLM Inference Engine Explained (KV Cache, Batching, vLLM)
Fun with Learning Technology
2 görüntüleme · 12 sa. önce
 6:01
Prefill vs Decode: Why LLM Inference Is So Slow (GPU Bottlenecks Explained)
SkildCore
20 görüntüleme · 1 ay önce
 32:55
Scalable LLM Inference on Kubernetes With NVIDIA NIMS, LangChain, Milvus and Flu... Riccardo Freschi
The Linux Foundation
151 görüntüleme · 1 yıl önce
 22:09
LLM Inference Is a Memory Problem, Not a Compute One
DevOps & AI Toolkit
5,2 B görüntüleme · 2 ay önce
 27:01
Rolling Out LLM Inference Engines on Kubernetes: Capacity, Topology, and... Meng Dong & Zihan Zheng
CNCF [Cloud Native Computing Foundation]
67 görüntüleme · 2 gün önce
 5:28
How Much GPU Memory is Needed for LLM Inference?
AppliedAI
7,4 B görüntüleme · 2 yıl önce
 34:14
Understanding the LLM Inference Workload - Mark Moyou, NVIDIA
PyTorch Foundation
36 B görüntüleme · 2 yıl önce
 19:39
GPU Architecture for LLM Inference: Memory, Bandwidth & Hardware Explained
Linear Digressions
144 görüntüleme · 13 gün önce
 6:56
Inside LLM Inference: GPUs, KV Cache, and Token Generation
AI Explained in 5 Minutes
2,9 B görüntüleme · 11 ay önce
 1:25
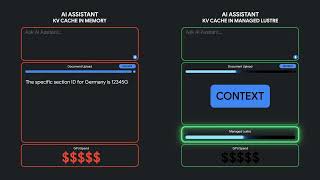
Google Cloud Managed Lustre for LLM Inference: Cut GPU Waste by 50%
DDN
156 görüntüleme · 6 ay önce
 31:00
How to Run Mistral 7B on a GPU | LLM Inference Explained | Part 8
Skillcef
70 görüntüleme · 1 ay önce
 23:34
LLM Inference Lecture: Roofline Analysis for GPU (arithmetic intensity, compute and memory bound)
Faradawn Yang
2,4 B görüntüleme · 9 ay önce
 10:55
LLM Inference Optimization Explained | Quantization, Batching & Parallelism
Micro Learning
387 görüntüleme · 4 ay önce
 32:45
Learn How to Run an LLM Inference Performance Benchmark on NVIDIA GPUs - DevConf.US 2025
DevConf
618 görüntüleme · 1 yıl önce
 52:53
How LLM Inference Works: GPUs, KV Cache, Batching, Networking
LevelUP I.T.
74 görüntüleme · 12 gün önce
 33:39
Mastering LLM Inference Optimization From Theory to Cost Effective Deployment: Mark Moyou
AI Engineer
82 B görüntüleme · 1 yıl önce
 41:53
Why LLM Inference Wastes So Much GPU — And How vLLM Fixes It
Extreme Inference
402 görüntüleme · 2 ay önce
 56:57
From GPU Bottlenecks to Smooth Chat: Cost-Efficient Architectures for LLM Inference :: Eshcar Hillel
CoreCppIL
130 görüntüleme · 8 ay önce
 13:31
AI Infrastructure Explained GPUs, vLLM, LLM D & How LLM Inference Works
ShowMixed IT
203 görüntüleme · 12 gün önce
Yüklenemedi. Lütfen tekrar deneyin.