Arama sonuçları
Lecture 60 Optimizing Linear Attention
 1:07:39
Lecture 60: Optimizing Linear Attention
GPU MODE
6,4 B görüntüleme · 1 yıl önce
 30:49
Introduction to linear attention
AIDAS Lab
777 görüntüleme · 8 ay önce
 34:32
Beyond Softmax — Linear Attention
Jia-Bin Huang
57 B görüntüleme · 10 ay önce
 1:27:08
Linear Attention and Beyond (Interactive Tutorial with Songlin Yang)
Sasha Rush
15 B görüntüleme · 1 yıl önce
 10:10
Linear Attention Explained: Fixing the O(n²) Cost of Transformers
Softmaxedd
378 görüntüleme · 1 ay önce
 53:19
LION: Linear Attention for Efficient Bidirectional Sequence Modeling - Arshia Afzal | ASAP 46
ASAP Seminar Series
191 görüntüleme · 1 yıl önce
 3:57
Linear Attention Mechanisms: From Retrieval to Regression | Unifying Mamba, RWKV, and Titans
Xiaol.x
277 görüntüleme · 9 ay önce
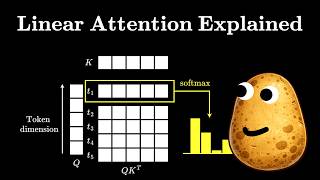 12:11
Linear Attention Explained from First Principles (Transformers → RNNs)
Kavishka Abeywardana
6,8 B görüntüleme · 9 ay önce
 3:24
Focused Linear Attention Explained in 3 Minutes!
Kavishka Abeywardana
883 görüntüleme · 9 ay önce
 8:56
Are Transformers Really RNNs? | Linear Attention Explained
Beyond the Abstract
53 görüntüleme · 2 hf. önce
 33:53
Linear Attention - Roadmap To Write AI Research Paper - Step by Step
Vuk Rosić
2,5 B görüntüleme · 11 ay önce
 13:37
30x Faster LINEAR Attention - No Softmax Trick
Vuk Rosić
839 görüntüleme · 1 yıl önce
 12:22
Hybrid Attention Explained: Gated DeltaNet + Full Attention
Agent Engineering
725 görüntüleme · 1 ay önce
 4:37
What is Flash Linear Attention?
Standarity
184 görüntüleme · 4 ay önce
 10:39
How Kimi K3 Rebuilt Attention
Convergence
326 görüntüleme · 3 ay önce
 11:34
Making AI Agents More Efficient with Linear Attention (Feat. Mamba State-Space models)
Faradawn Yang
495 görüntüleme · 10 ay önce
 23:03
Deep Learning Foundations by Soheil Feizi : Linear Attention
Soheil Feizi
2,8 B görüntüleme · 2 yıl önce
 1:10:08
7 AI Papers Explained From Intuition to Math | MoE, Muon, Linear Attention & Optimization
Xiaol.x
221 görüntüleme · 3 ay önce
 5:55
NVIDIA fixed a FLAW in LINEAR ATTENTION nobody was talking about (Gated DeltaNet-2)
Machine Learning With Aaryan
379 görüntüleme · 5 ay önce
 24:05
60. IEA: Introduction to nonlinear programming and nonnegativity restrictions
Lazarski Open Courses
331 görüntüleme · 3 yıl önce
Yüklenemedi. Lütfen tekrar deneyin.